Cadence launched the Maestro AI Model Portfolio on October 26, 2026, introducing domain-specialized models that deliver up to 30% higher quality of results and up to 5x greater token efficiency versus general-purpose foundation models. The portfolio integrates with Cadence AI Super Agents and reinforcement learning loops across its EDA and SDA toolchain, marking a deliberate pivot from point-tool vendor to vertically integrated agentic design platform. Maestro positions Cadence at the center of the next generation of chip design infrastructure.
What Is Covered in This Article:
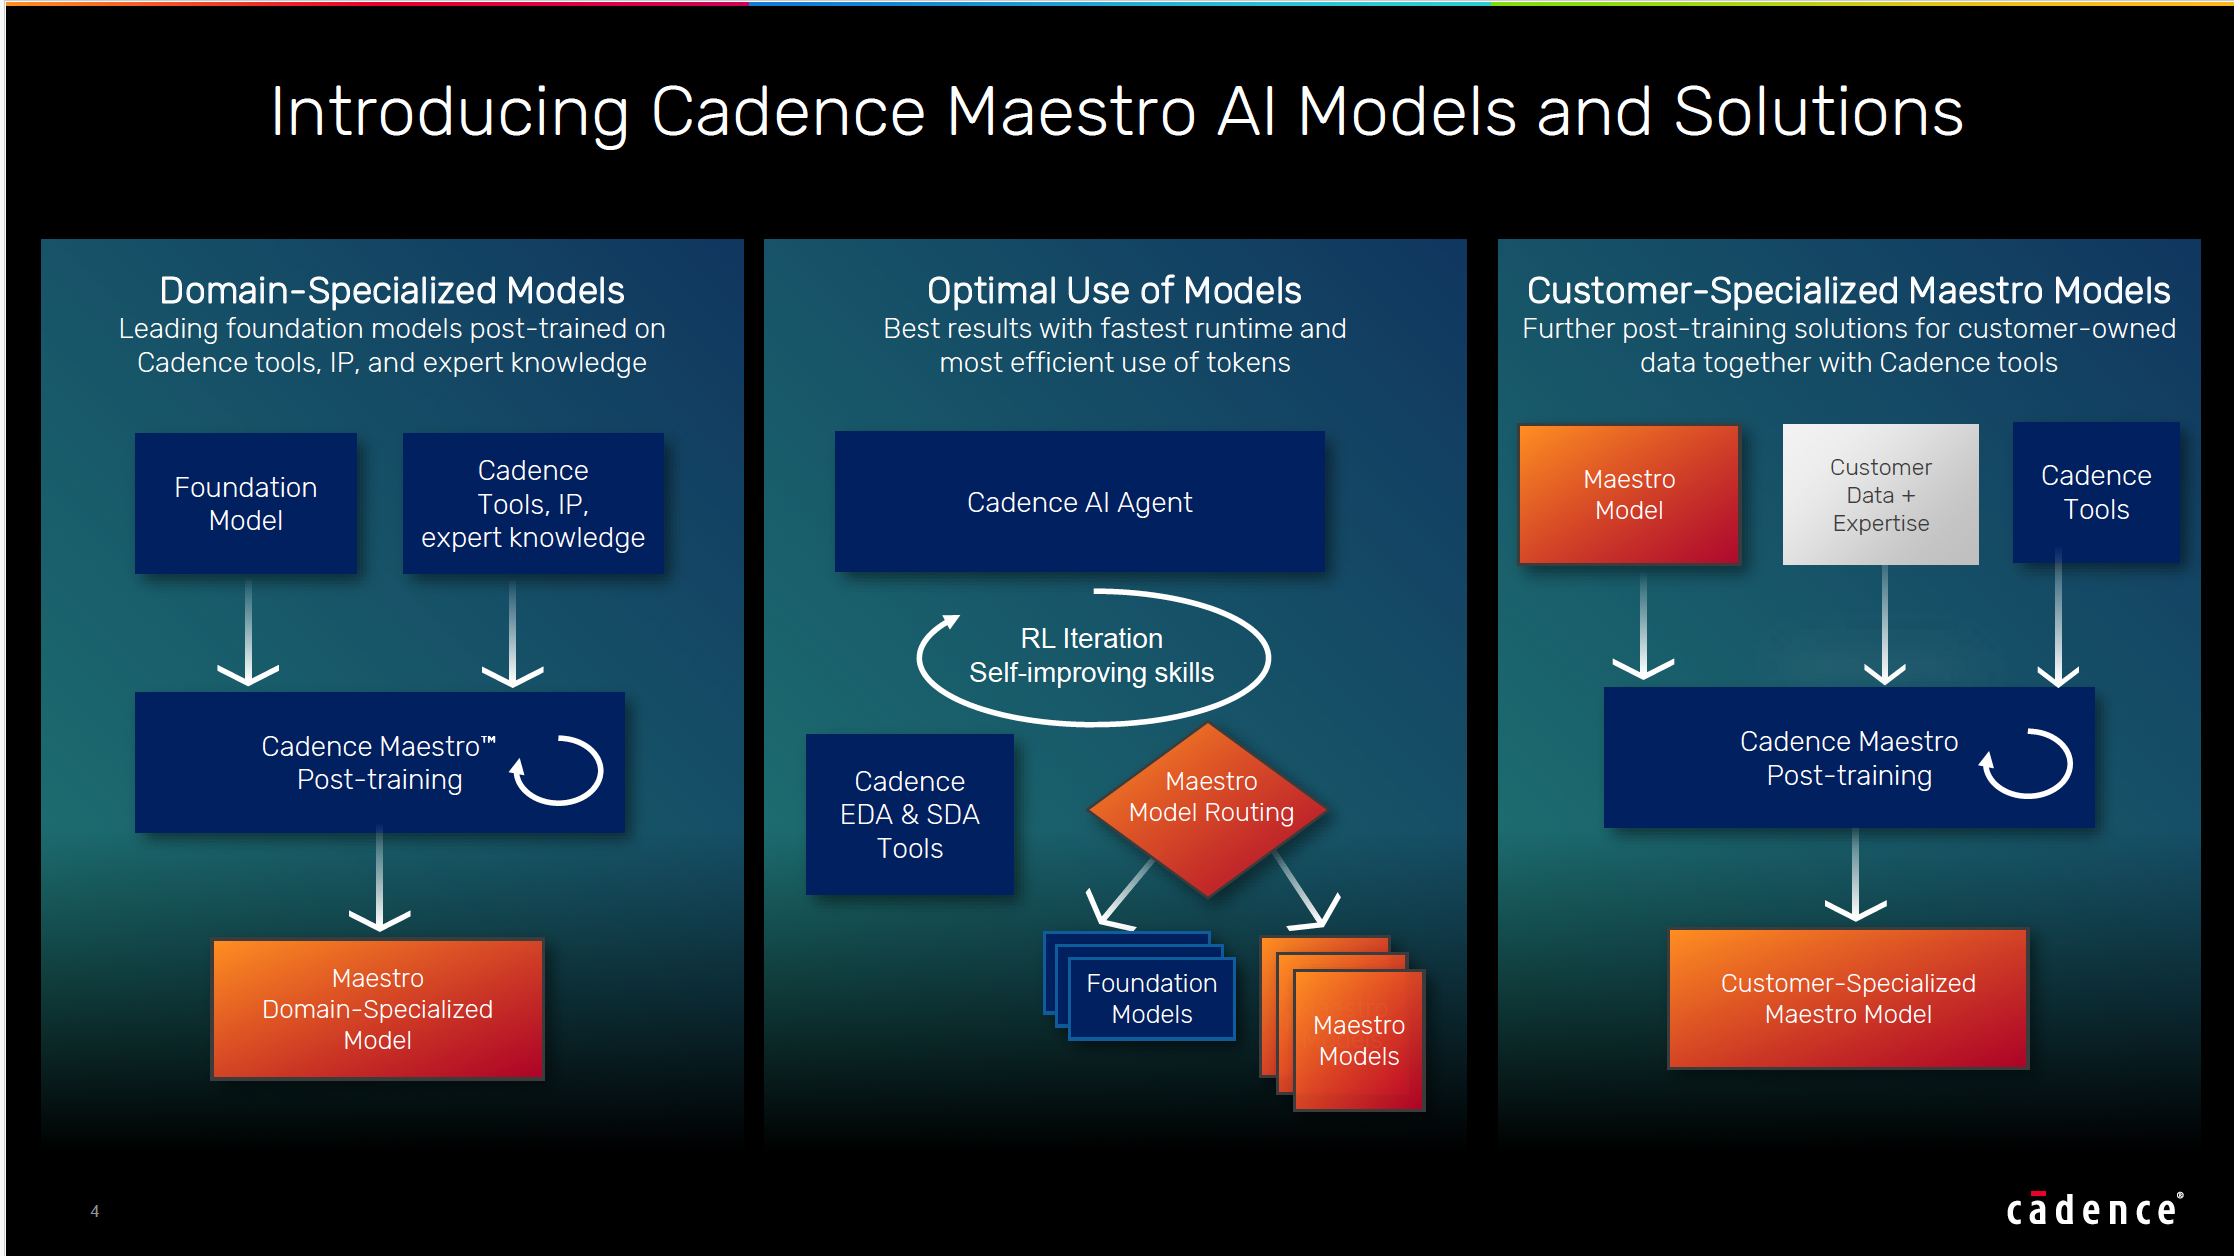
- Maestro, a domain-specialized AI model portfolio powering Cadence AI Super Agents across chip and system design
- A vertically integrated reinforcement learning environment linking Maestro models, AI Super Agents, and Cadence EDA and SDA tools
- Initial design workflow results of up to 30% higher quality and up to 5x greater token efficiency versus general purpose foundation models
- Customer-specialized post-training and multi-model routing across frontier, open-weight, and Maestro models
- Early access for select customers in Q4 2026 with NVIDIA, Socionext, and Silicon Labs engagement
The News: Cadence (Nasdaq: CDNS) announced the Maestro AI Model Portfolio on October 26, a family of domain-specialized AI models that powers its AI Super Agents across semiconductor and system design workflows. The portfolio spans multiple model sizes and architectures, combining post-trained large language models, trained decision models, and self-improving agent skills. Maestro powers the AI Super Agents Cadence has introduced since early 2026, including ChipStack, InnoStack, AuraStack, and ViraStack, and connects them to Cadence EDA and system design automation (SDA) tools through reinforcement learning (RL) loops. Cadence reports initial design-workflow results of up to 30% higher quality of results and up to 5x greater token efficiency versus a general purpose foundation model.
Cadence’s deterministic solvers and evaluation harnesses score agent outputs against engineering objectives, constraints, and ground truth, closing the RL feedback loop. NVIDIA is contributing its Nemotron models and OpenShell agent security architecture. “By grounding reinforcement learning in feedback from EDA tools and deterministic solvers, we can teach agents to make better design decisions,” said Tim Costa, Vice President and General Manager of Industrial and Computational Engineering at NVIDIA. Socionext is deploying InnoStack in production and expects up to 5x overall productivity gains. Maestro models can be further post-trained on a customer’s proprietary data, deployed in cloud or on-premises environments, and reach select early access customers in the fourth quarter of 2026.
Cadence Maestro Puts Frontier-Class Reinforcement Learning Behind Chip Design Agents
Analyst Take: Maestro moves Cadence up the AI stack. Futurum has argued that software vendors whose tools can verify an AI’s work would run the RL loop on their own instead of waiting for the labs and Maestro converts that thesis into product. Software vendors have post-trained models for their own platforms, with ServiceNow’s Apriel family the clearest precedent, and Cadence is the first to sell the loop itself, RL post-training offered to customers and grounded in its own tools. Domain-specialized models give Cadence agents a supplement to frontier inference, with routing assigning each design task to the cheapest model that can complete it well.
Only the Tool Owner Can Scale RL Rollouts For Its Own Tools
The scarce input for reinforcement learning at scale is a verifier that can score an agent’s work automatically. Futurum’s CoreWeave Fully Connected 2026 coverage found frontier lab RL becoming a managed service while reward design stays with the customer, the step that gates enterprise adoption. Cadence closes that gap within one vertical. Few domains are as verifiable as chip design, where simulation and signoff return deterministic verdicts against ground truth. A harness around licensed tools stops at the tool boundary, and Cadence told Futurum in a pre-launch briefing that it rebuilt interfaces designed for human interaction into interfaces agents call, the prerequisite for iterating tool and model together. Rollouts run at zero marginal cost with in-house designers and proprietary design data, volumes a lab would need a license agreement to approach, and customer-specialized training happens on premises, so the data never leaves.
Specialized Models Supplement Frontier Inference Through Routing
Cadence AI Super Agents decompose a high-level objective and route each step across Maestro models, frontier commercial models, and open-weight baselines. The economics drive the design. Long-running autonomous tasks, such as root-causing regression failures or converging timing and power goals, multiply token consumption, and running every step on a frontier model prices autonomy out of production use. The up to 5x token efficiency claim, if it reproduces in customer flows, addresses the binding constraint on mass deployment of autonomous agents.
Customer Post-Training Drives Usage Revenue Beyond the Service Fee
The third pillar extends the post-training framework to customer data. Maestro models can be further specialized on a customer’s proprietary designs, workflows, and expertise, with Cadence supplying the harness and the know-how, a services business adjacent to the license model. The specialization fee matters less than what it releases. A specialized model that reduces token cost makes long-running autonomous agents affordable at scale, and every agent that becomes affordable multiplies tool invocations, which consume licenses, cloud compute, and Super Agent capacity. The offset is cannibalization, since routing work to cheaper models lowers revenue per task, and the Cadence bet is that task volume grows faster. Futurum sees the education burden as the near-term gate, because buyers who equate RL post-training with supervised fine-tuning or context engineering will undervalue it. Named customer-specialized engagements are the evidence to watch through 2027.
NVIDIA Supplies the Whole Category While Synopsys Contests the Same Ground
NVIDIA contributes Nemotron base models, agent sandboxing and governance through the OpenShell Reference Architecture it launched at GTC Berlin last week, and engineering expertise from its own training work. The division of labor is the tell, because NVIDIA is the most sophisticated chip design customer in the world and still needs Cadence’s environment for verified rewards, and it also works with Synopsys on agentic design, collecting from whoever performs best. Synopsys launched Autopilot in September 2026 and is driving AgentEngineer toward general availability by year end with AMD and Microsoft deployments, and it owns its own verifiers and license base, so the separation between the EDA leaders today is execution measured in quarters. The AI labs press from below, since EDA tasks have become a benchmark target and design houses already pull credible RTL from base models. The bear case is concentrated in validation. The 30% and 5x figures are Cadence internal, early access begins in Q4 2026 with select customers, and the claims remain a thesis until production deployments convert them into evidence.
What to Watch:
- Whether early access deployments confirm the up to 30% quality and up to 5x token-efficiency claims in customer production flows
- Whether Cadence names customer-specialized Maestro engagements and their commercial terms through Q4 2026 and early 2027
- Whether Synopsys pairs AgentEngineer general availability with domain-specialized models of its own
- Whether Maestro gains persist as new frontier and open-weight base models are released
- Whether AI labs expand direct EDA fine-tuning efforts that bypass vendor post-training services
Read more details about Maestro AI Model Portfolio on the Cadence website.
Sources
Declaration of generative AI and AI-assisted technologies in the writing process: This content has been generated with the support of artificial intelligence technologies. Due to the fast pace of content creation and the continuous evolution of data and information, The Futurum Group and its analysts strive to ensure the accuracy and factual integrity of the information presented. However, the opinions and interpretations expressed in this content reflect those of the individual author/analyst. The Futurum Group makes no guarantees regarding the completeness, accuracy, or reliability of any information contained herein. Readers are encouraged to verify facts independently and consult relevant sources for further clarification.
Disclosure: Futurum is a research and advisory firm that engages or has engaged in research, analysis, and advisory services with many technology companies, including those mentioned in this article. The author does not hold any equity positions with any company mentioned in this article.
Analysis and opinions expressed herein are specific to the analyst individually and data and other information that might have been provided for validation, not those of Futurum as a whole.
Read the full Futurum Group Disclosure.
Other Insights From Futurum:
Nokia Designs Network Hardware 5x Faster on Cadence’s Agentic Supercomputer
Cadence Opens Europe’s First Sovereign AI Platform for Chip and AI Factory Design With NVIDIA
TSMC’s OIP Forum Turns Agentic Chip Design Demos Into Production Flows
Author Information
Brendan is Research Director, Semiconductors, Supply Chain, and Emerging Tech. He advises clients on strategic initiatives and leads the Futurum Semiconductors Practice. He is an experienced tech industry analyst who has guided tech leaders in identifying market opportunities spanning edge processors, generative AI applications, and hyperscale data centers.
Before joining Futurum, Brendan consulted with global AI leaders and served as a Senior Analyst in Emerging Technology Research at PitchBook. At PitchBook, he developed market intelligence tools for AI, highlighted by one of the industry’s most comprehensive AI semiconductor market landscapes encompassing both public and private companies. He has advised Fortune 100 tech giants, growth-stage innovators, global investors, and leading market research firms. Before PitchBook, he led research teams in tech investment banking and market research.
Brendan is based in Seattle, Washington. He has a Bachelor of Arts Degree from Amherst College.