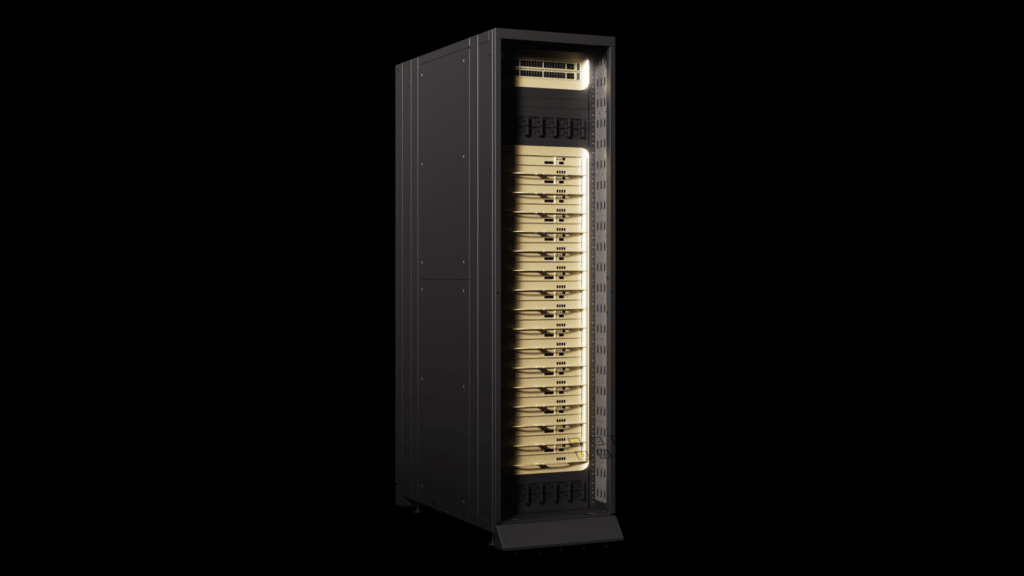
The News: The NVIDIA A100 Tensor Core GPU has landed on Google Cloud. Available in alpha on Google Compute Engine just over a month after its introduction, A100 has come to the cloud faster than any NVIDIA GPU in history.
Today’s introduction of the Accelerator-Optimized VM (A2) instance family featuring A100 makes Google the first cloud service provider to offer the new NVIDIA GPU. Read the full release on NVIDIA’s blog.
Analyst Take: The most recent launch from Jensen Huang and NVIDIA was material in its impact to break throughs in performance, speed, power consumption and footprint. Seeing what used to take dozens of racks being done in 1 RU with a significant economic advantage also caught my attention.
Quick Review of the NVIDIA A100 Tensor Core GPU
The A100 is built on the newly introduced NVIDIA Ampere architecture and arguably it delivers NVIDIA’s greatest generational improvement ever (shouldn’t they all?). It claims a boost in training and inference computing performance by 20x over its predecessors, providing material speedups for workloads to power the growth in AI that is expected in immediate future.
The Offering: NVIDIA A100 Tensor Core GPU on Google Cloud
In terms of performance, according to the NVIDIA, The new A2 VM instances are designed to give users flexibility and are capable of delivering different levels of performance to efficiently accelerate workloads across CUDA-enabled machine learning training and inference, data analytics, as well as high performance computing.
From a specifications standpoint, customers can go from small to large depending on performance needs. For the largest and most demanding workloads, Google Compute Engine will offer its customers what is referred to as the a2-megagpu-16g instance, which comes with 16 A100 GPUs, offering a total of 640GB of GPU memory and 1.3TB of system memory — all connected through NVSwitch with up to 9.6TB/s of aggregate bandwidth. However, users with lesser demands can choose options with a single GPU or in configurations of 2, 4 or 8 as well as the above mentioned 16. (Specs per NVIDIA)
Fast to Market: Google Cloud Wins the Race with the NVIDIA A100
Over the past few years we have witness a faster and faster time to market with improved AI acceleration technologies. It went from years to months and it is looking like in the future it may be just a matter of weeks. When NVIDIA’s K80 GPU made it to AWS it took about two years. More recently Volta made it to AWS in about 5 months. So the speed in which this made it to Google is impressive being able to introduce the new A2 in less than two months after Ampere’s arrival. I also believe the more rapid time from GPU chip launch to cloud adoption is a clear indicator that there is a significant increase in demand for HPC in the cloud, driven by the growth in AI workloads.
Additionally, Google Cloud announced that it will be offering Nvidia A100 support for Google Kubernetes Engine, Cloud AI Platform, and other services. This will be material as hybrid and multi-cloud continues to gain momentum.
Google Cloud is First, but not the only for the NVIDIA A100
Based on statements included in the Ampere launch, I’m confident that the adoption of the A100 will follow with other prominent cloud vendors getting on board including Amazon Web Services (AWS), Microsoft Azure, Tecnent Cloud, Baidu Cloud, and Alibaba Cloud.
Overall Impressions of NVIDIA landing its A100 on Google Cloud
Earlier this summer when NVIIDA announced its new Ampere, it was quickly evident that the next generation architecture was going to have an immediate impact on acceleration of workloads–and the cloud would undoubtedly benefit.
While Google is smaller than its largest competitors in AWS and Microsoft, it has established a reputation for its cutting edge focus on AI services. Being the first to be able to offer the new A100 will certainly be well received by Google’s users and could serve as a catalyst to attracting some new customers to the Google Cloud.
Having said that, as I mentioned above, I’m sure that it is a matter of time before we see this architecture adopted by AWS and Azure as well as other hyperscale cloud providers like China’s Baidu, Tencent and Alibaba. So Google Cloud will need to be swift in taking advantage of its temporary lead in availability of NVIDIA’s new A100 Tensor Core GPU.
Futurum Research provides industry research and analysis. These columns are for educational purposes only and should not be considered in any way investment advice.
Read more analysis from Futurum Research:
Oracle Announces Its Fully Managed Region Cloud@Customer
Qualcomm Updates its Popular Snapdragon 865 5G Platform
Microsoft Announces Launch of Global Digital Skills Initiative Serving 25 Million by Year End
Image Credit: NVIDIA
Author Information
Daniel is the CEO of The Futurum Group. Living his life at the intersection of people and technology, Daniel works with the world’s largest technology brands exploring Digital Transformation and how it is influencing the enterprise.
From the leading edge of AI to global technology policy, Daniel makes the connections between business, people and tech that are required for companies to benefit most from their technology investments. Daniel is a top 5 globally ranked industry analyst and his ideas are regularly cited or shared in television appearances by CNBC, Bloomberg, Wall Street Journal and hundreds of other sites around the world.
A 7x Best-Selling Author including his most recent book “Human/Machine.” Daniel is also a Forbes and MarketWatch (Dow Jones) contributor.
An MBA and Former Graduate Adjunct Faculty, Daniel is an Austin Texas transplant after 40 years in Chicago. His speaking takes him around the world each year as he shares his vision of the role technology will play in our future.