Analyst(s): Brendan Burke
Publication Date: September 14, 2026
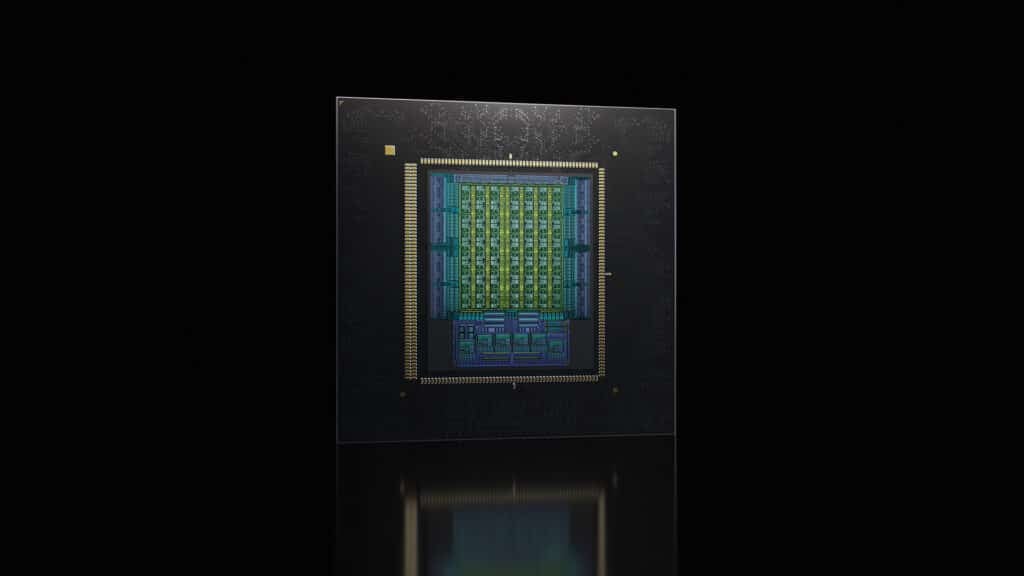
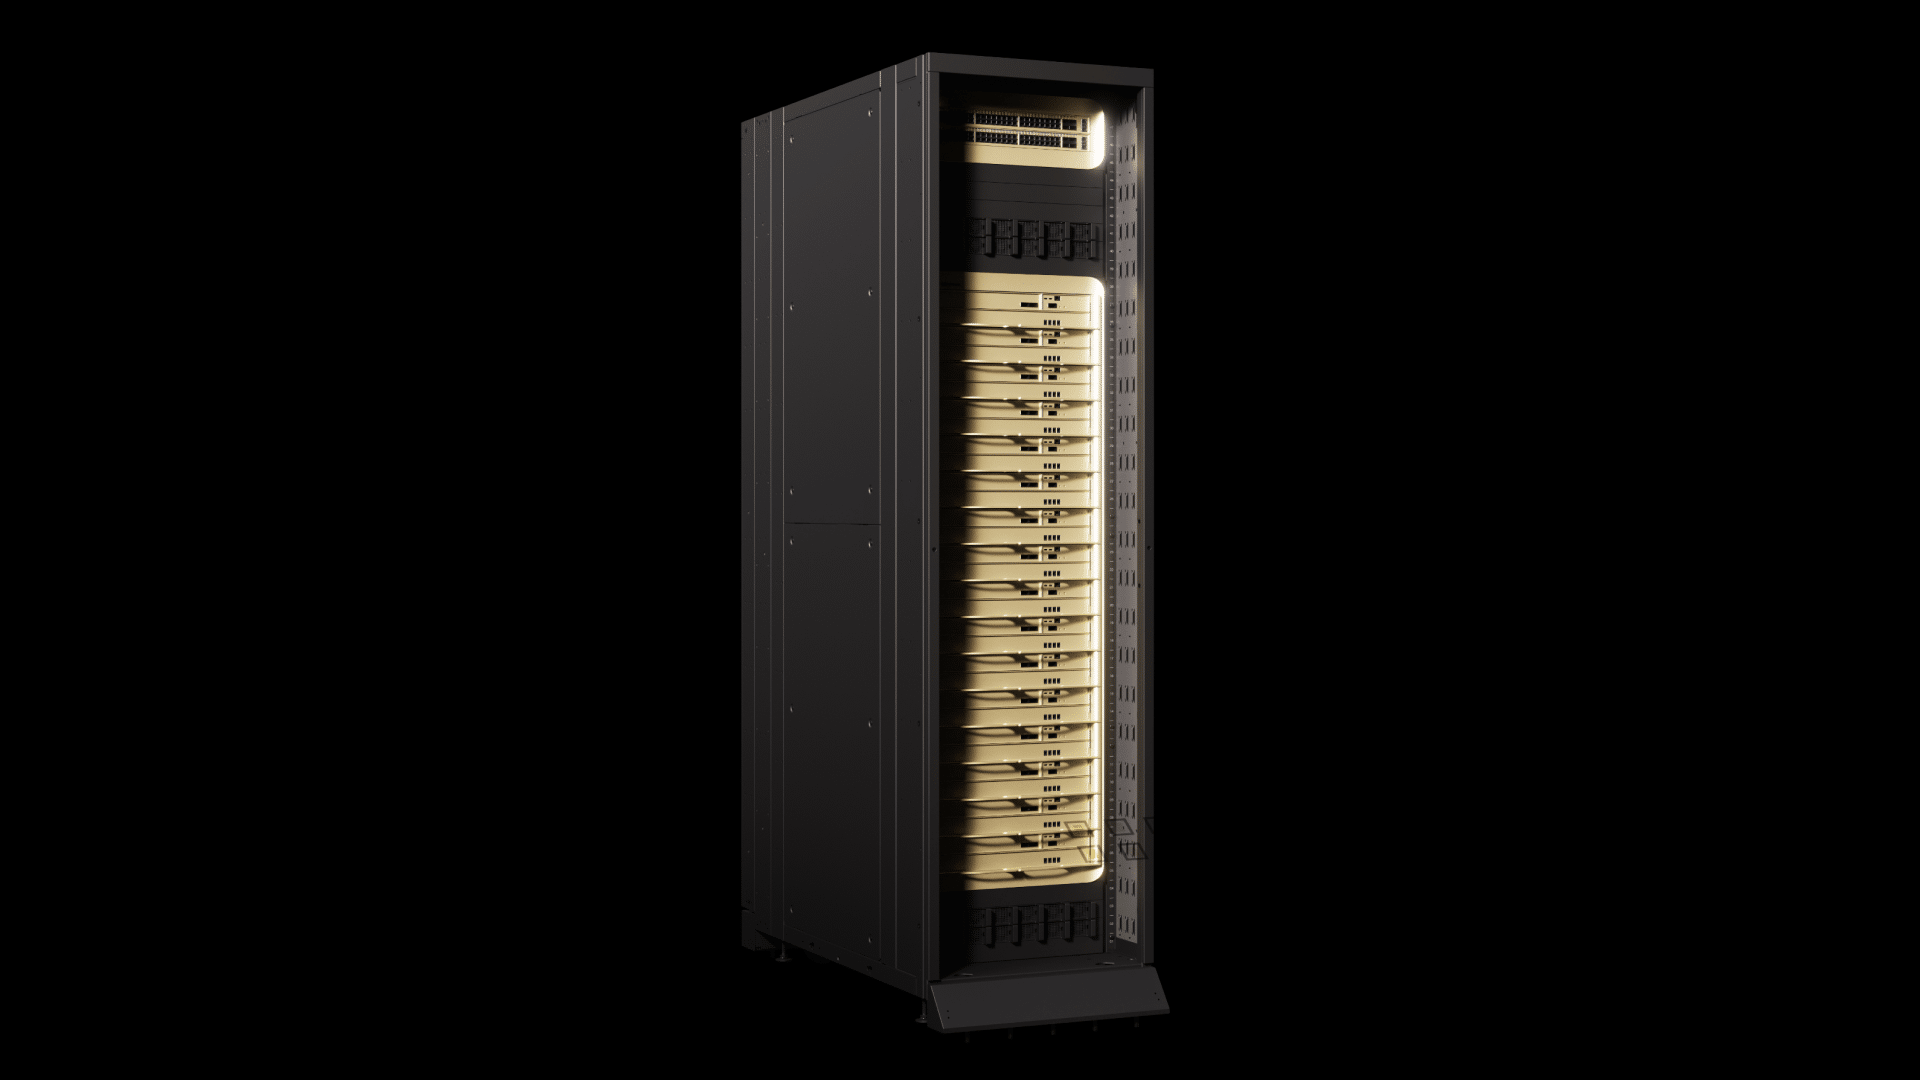
NVIDIA has moved Groq 3 LPX into full production as a specialized inference accelerator for Vera Rubin. The launch strengthens NVIDIA’s position in low-latency decode, although production performance and cloud economics will determine its commercial value.
What Is Covered in This Article:
- Groq 3 LPX full-production launch and early AI cloud adoption
- Specialized decode for agentic AI workloads
- Groq acquisition and competition from AMD and Cerebras
- Heterogeneous rack integration and operational execution
- Premium token pricing and cloud-service economics
The News: NVIDIA announced that Groq 3 LPX entered full production as an interactive AI inference accelerator for the Vera Rubin platform. The rack-scale offering targets low-latency token generation for agentic workloads and works alongside Vera Rubin NVL72 across different inference stages.
Artificial Analysis measured 3,431 output tokens per second on Gemma 4 31B at 100K context, which NVIDIA said delivered 4x faster responsiveness than the nearest alternative platform. Details shared during NVIDIA’s Hot Chips presentation underscored how Groq 3 LPX employs external-drafter speculative decoding to achieve these speeds alongside Vera Rubin GPUs. Nebius plans to become the first adopter through its production inference platform, while a purpose-built inference cloud provider plans to follow as an early adopter.
NVIDIA Groq 3 LPX’s Promise of World’s Fastest Inference Enters Full Production
Analyst Take: NVIDIA Groq 3 LPX signals that the next inference contest will center on matching processors to specific stages of an agentic workload, not forcing every stage onto a general-purpose accelerator. NVIDIA has positioned LPX beside Vera Rubin NVL72, assigning latency-sensitive generation to Groq technology while retaining GPUs for context processing, prefill, and broader AI workloads. This approach strengthens the Vera Rubin platform because it incorporates specialized decoding without asking customers to replace the NVIDIA infrastructure around it. The launch also turns NVIDIA’s $20 billion purchase of Groq assets into a production offering only eight months after the transaction. NVIDIA has made the correct architectural move, but cloud deployment will determine whether specialization creates durable value or merely adds another processor to the rack.
Specialized Decode Strengthens the NVIDIA Platform
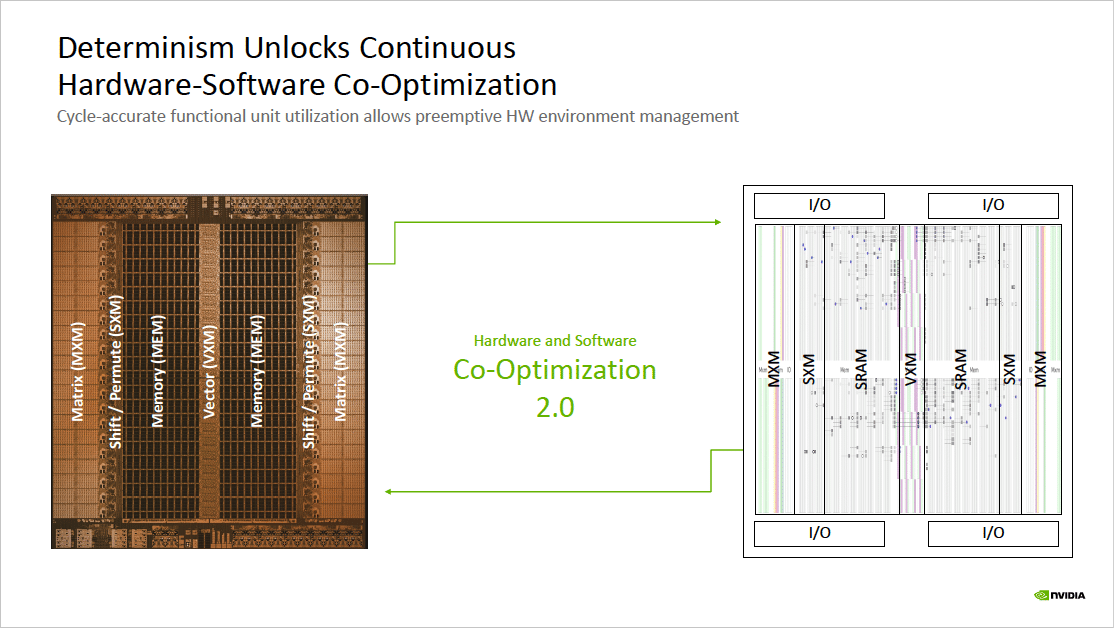
Agentic workloads make generation latency a platform issue because every reasoning step, tool call, code test, and verification cycle adds time to the user experience. NVIDIA’s decision to separate decode from other inference stages acknowledges that one processor does not execute every part of an agent loop equally well. The 3,431-token-per-second result at 100K context supports that decision because it combines high output speed with the long context required for extended coding and multi-agent sessions. Its architecture relies on flat SRAM memory, a deterministic compiler with software-scheduled data movement across east-west high-bandwidth streams, and matrix multiply units (MXM) that saturate compute at low batch sizes to achieve extremely low-latency token generation. NVIDIA Groq 3 LPX strengthens Vera Rubin by filling a performance gap that a GPU-only configuration would otherwise leave open to specialized competitors.
NVIDIA Is Absorbing the Standalone Inference Challenge
The acquisition of Groq assets gave NVIDIA a direct response to inference architectures that compete on decode speed rather than GPU flexibility. Bringing the technology into full production within eight months prevents NVIDIA from conceding the highest-interactivity segment while Vera Rubin shipments ramp. NVIDIA can now offer GPUs, LPUs, CPUs, networking, storage, and data processing infrastructure within one coordinated platform, which shifts the competitive discussion from individual chip performance to workload placement across the rack. AMD’s plan to integrate Cerebras chips into its rack-scale systems confirms that specialized inference will not remain an uncontested NVIDIA category. NVIDIA’s competitive position will depend on making these processor classes operate as one coordinated platform rather than relying on LPX performance in isolation.
Heterogeneous Compute Raises the Execution Standard
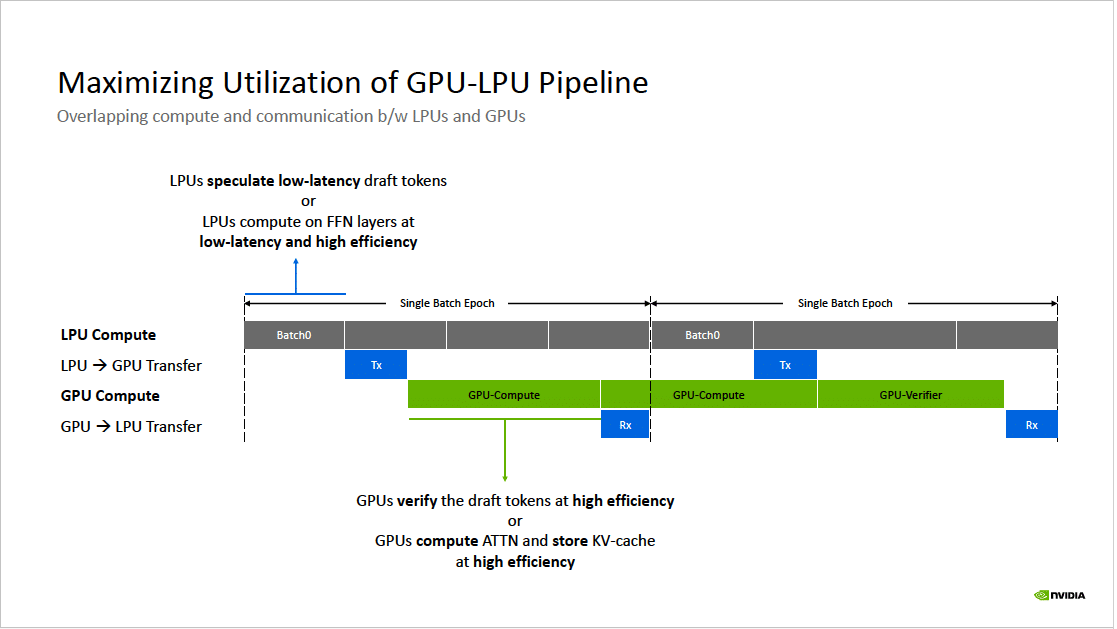
Adding LPX expands Vera Rubin’s capabilities, but it also makes coordination across processors the central execution requirement. At Hot Chips, NVIDIA highlighted external-drafter speculative decoding as a key mechanism for heterogeneous compute, where Groq 3 LPX rapidly generates candidate tokens while Vera Rubin NVL72 GPUs handle target model verification. The key benefits of speculative decoding in this system include dramatically reduced inter-token latency, relieved memory bandwidth bottlenecks on GPUs, and maximized throughput per watt without sacrificing output quality. These options give cloud providers flexibility across prefill-decode and attention-FFN disaggregation, provided data movement and workload scheduling do not erode the latency gained during decode.
NVIDIA Groq 3 LPX Must Turn Speed Into Cloud Economics
Groq 3 LPX creates commercial value only if cloud providers can monetize faster token generation rather than absorb the additional infrastructure within existing service tiers. Nebius plans to offer LPX through an API that developers already use, creating a direct test of demand without requiring customers to migrate to another software stack. Futurum’s 1H 2026 Data Center Semiconductors Market Sizing & Five-Year Forecast projects inference-focused servers rising from roughly half of the 2025 market to 73%, or $884.9 billion, by 2030, making differentiated inference performance strategically valuable. NVIDIA argues that providers can charge more for latency-sensitive tokens, yet we have heard that the LPX rack can be quoted as high as $1 million, increasing the premium that customers must accept to produce an ROI. NVIDIA Groq 3 LPX will strengthen the company’s commercial position only if faster generation reduces agent completion times enough to produce attractive cloud economics.
What to Watch:
- The first AI cloud deployment with Nebius, later in 2026, should establish whether Groq 3 LPX maintains its benchmark speed under live concurrency, service-level commitments, and long-running agent sessions.
- NVIDIA needs to show that prefill-decode disaggregation, attention-FFN disaggregation, and external-drafter speculative decoding reduce total agent completion time rather than improving only the decode stage.
- Cloud pricing will reveal whether users will pay more for faster tokens or expect higher responsiveness within existing inference tiers.
- Production deployments should verify whether NVIDIA’s throughput-per-watt claims hold under comparable workloads, rack configurations, and utilization levels.
- Coordinating Samsung-manufactured Groq chips with TSMC-manufactured GPUs and NVIDIA’s wider rack infrastructure will test the operational value of the seven-chip, five-rack Vera Rubin design.
See the complete announcement on Groq 3 LPX entering full production on the NVIDIA website.
Declaration of generative AI and AI-assisted technologies in the writing process: This content has been generated with the support of artificial intelligence technologies. Due to the fast pace of content creation and the continuous evolution of data and information, The Futurum Group and its analysts strive to ensure the accuracy and factual integrity of the information presented. However, the opinions and interpretations expressed in this content reflect those of the individual author/analyst. The Futurum Group makes no guarantees regarding the completeness, accuracy, or reliability of any information contained herein. Readers are encouraged to verify facts independently and consult relevant sources for further clarification.
Disclosure: Futurum is a research and advisory firm that engages or has engaged in research, analysis, and advisory services with many technology companies, including those mentioned in this article. The author does not hold any equity positions with any company mentioned in this article.
Analysis and opinions expressed herein are specific to the analyst individually and data and other information that might have been provided for validation, not those of Futurum as a whole.
Read the full Futurum Group Disclosure.
Other Insights From Futurum:
NVIDIA Q2 FY 2027: AI Infrastructure Demand Extends Into FY 2028
NVIDIA’s Credit Support Buys Exclusivity at OpenAI’s Ohio Data Center
How NVIDIA is Building a Critical Safety Layer for Physical AI
Featured Image: NVIDIA
Author Information
Brendan is Research Director, Semiconductors, Supply Chain, and Emerging Tech. He advises clients on strategic initiatives and leads the Futurum Semiconductors Practice. He is an experienced tech industry analyst who has guided tech leaders in identifying market opportunities spanning edge processors, generative AI applications, and hyperscale data centers.
Before joining Futurum, Brendan consulted with global AI leaders and served as a Senior Analyst in Emerging Technology Research at PitchBook. At PitchBook, he developed market intelligence tools for AI, highlighted by one of the industry’s most comprehensive AI semiconductor market landscapes encompassing both public and private companies. He has advised Fortune 100 tech giants, growth-stage innovators, global investors, and leading market research firms. Before PitchBook, he led research teams in tech investment banking and market research.
Brendan is based in Seattle, Washington. He has a Bachelor of Arts Degree from Amherst College.