Analyst(s): Alastair Cooke
Publication Date: July 29, 2026
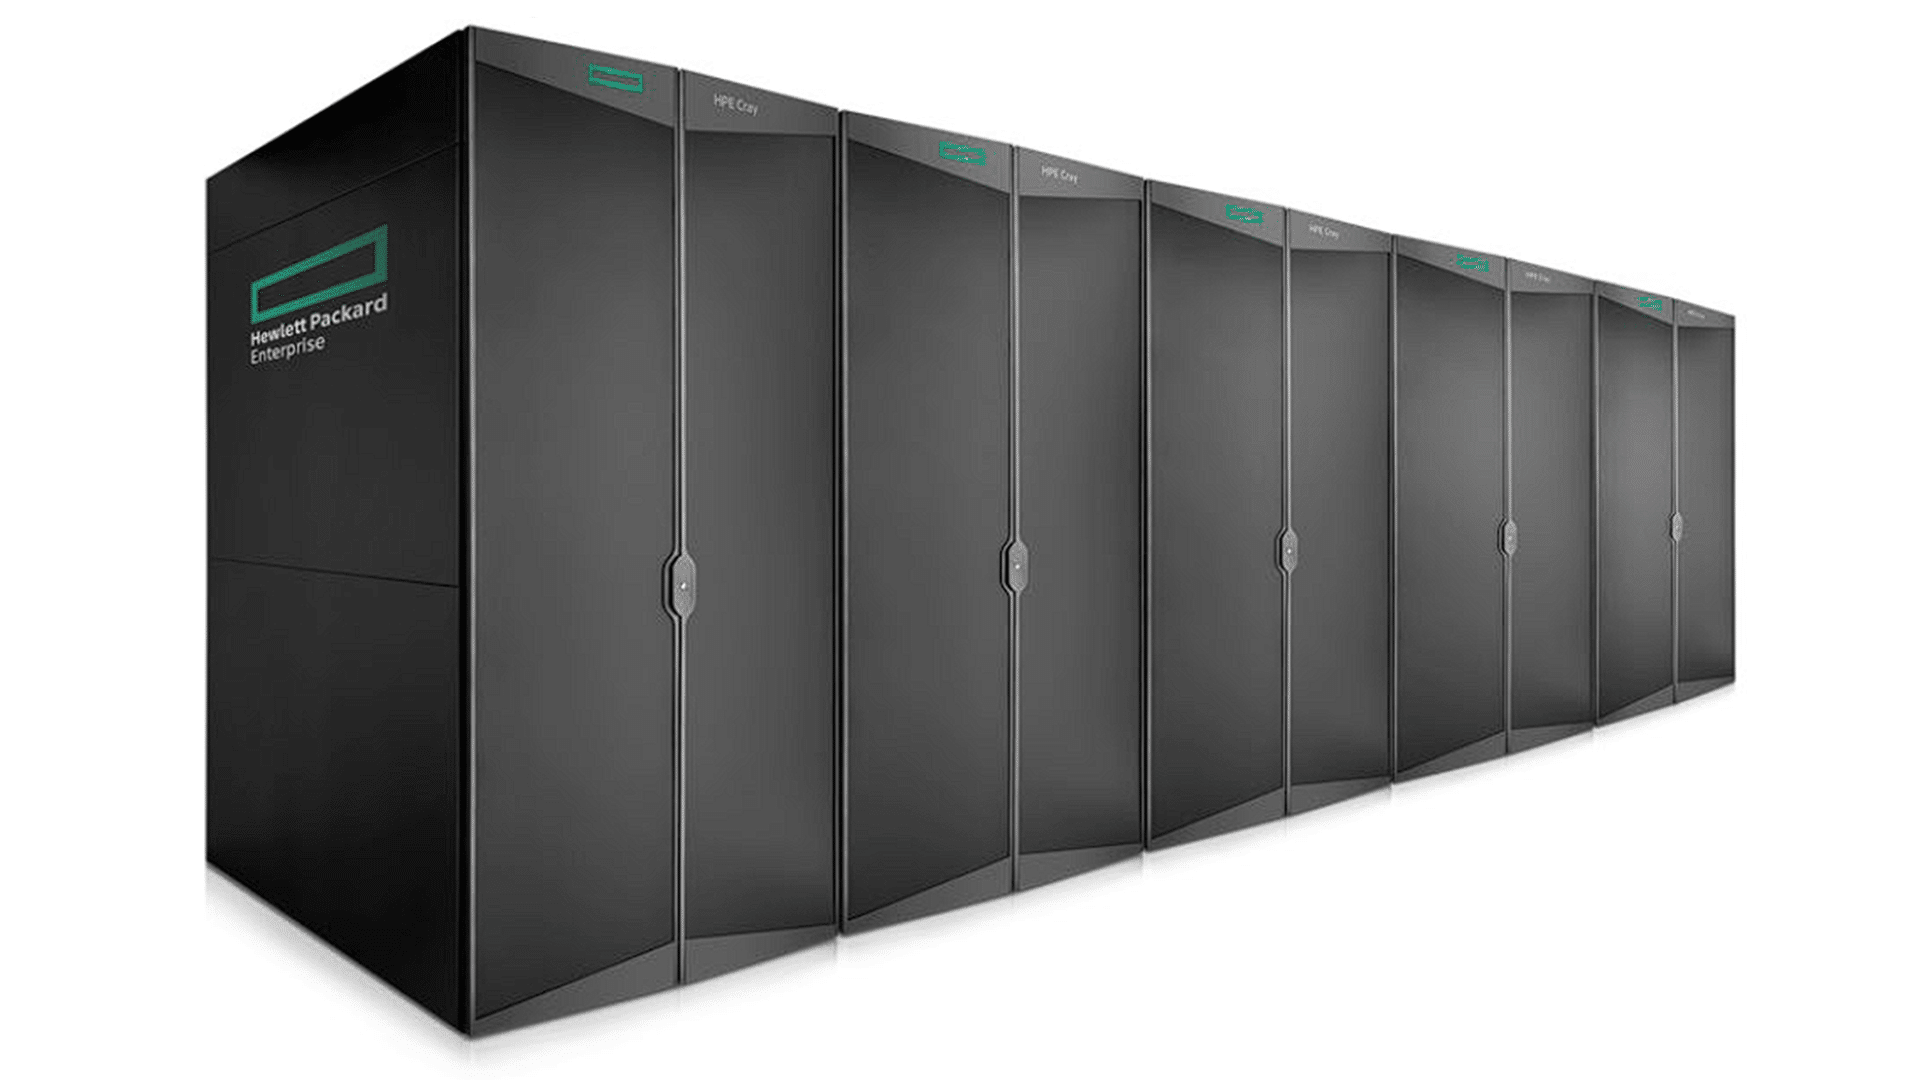
HPE unveiled the Cray Supercomputing GX5000, powered by 6th Gen AMD EPYC processors, claiming 40% higher core density per rack than the nearest competing system. Oak Ridge National Laboratory and Germany’s HLRS are among the first organizations deploying GX5000-based systems for AI and quantum-adjacent research.
What Is Covered in This Article:
- HPE launched the Cray Supercomputing GX5000, featuring 6th Gen AMD EPYC processors and claiming the industry’s highest compute density per rack.
- Oak Ridge National Laboratory and the University of Stuttgart’s HLRS are named as early adopters building GX5000-based systems.
- HPE and AMD are also collaborating on the Helios AI rack-scale system, which uses Ethernet-based scale-up networking.
The News: HPE introduced the HPE Cray Supercomputing GX5000 at AMD’s Advancing AI 2026 event in San Francisco on July 23, 2026. The system, featuring 6th Gen AMD EPYC processors, delivers 81,920 CPU cores per rack, 40% more than Supermicro’s Flex Twin, the next-densest system on the market, according to HPE. HPE said the GX5000 also reduces data center floor space by 25% and supports facility water temperatures 25% warmer than prior systems, up to 40°C, through its direct liquid cooling.
The GX5000 ships in two blade configurations: the GX350a Accelerated Blade, pairing one 6th Gen AMD EPYC processor with four AMD Instinct MI430X GPUs (up to 112 GPUs per rack), and the GX250 Compute Blade, a CPU-only design with eight 6th Gen AMD EPYC processors per node and up to 81,920 cores per rack for double-precision workloads.
Early adopters include Oak Ridge National Laboratory, which is building an exascale system called Discovery and a dedicated AI system called Lux as part of the U.S. Genesis Mission, and HLRS in Germany, which is building a GX5000-based system called Herder that HPE says will be seven times more powerful than HLRS’s current supercomputer. HPE also detailed a collaboration with AMD on the Helios AI rack-scale system, which uses HPE Juniper Networking hardware based on the Ultra Accelerator Link over Ethernet (UALoE) standard and is designed to deliver 260 TB/s of scale-up bandwidth and 2.9 exaflops of FP4 performance.
HPE’s GX5000 Delivers 40% Denser AI Supercomputing With AMD EPYC
Analyst Take: HPE Cray Supercomputing GX5000 arrives at a moment when density, not just raw throughput, has become the currency of AI infrastructure competition. HPE’s claim of 40% more AMD EPYC cores per rack than the nearest competing system is squarely aimed at hyperscalers and national labs that are running out of floor space and power headroom before they run out of budget.
Density as a Proxy for Power Efficiency
The GX5000’s pitch rests on three linked claims: more cores per rack, 25% less floor space, and warmer facility water tolerances up to 40°C. Warmer water thresholds matter more than they sound: they let data centers rely more on free cooling and less on chillers, which lowers the total power draw per compute unit delivered. For hyperscalers and national labs sizing next-generation AI clusters, the real constraint is increasingly power and cooling capacity rather than chip supply, so a system that claims to compress all three dimensions at once is a direct response to that bottleneck.
Two Blades, Two Audiences
By offering the GX350a (GPU-accelerated, mixed precision) and GX250 (CPU-only, double precision) as separate blades within the same rack architecture, HPE is explicitly trying to serve both AI training/inference customers and traditional HPC simulation customers from one platform family. That matters commercially: it lets HPE sell into the same national-lab accounts for both the AI workload and the physics-simulation workload it has served for decades, rather than ceding the AI side to GPU-centric competitors.
Ethernet as the Interconnect Bet
The more consequential move may be buried in the Helios collaboration: HPE and AMD are betting on Ultra Accelerator Link over Ethernet (UALoE) rather than a proprietary scale-up fabric. NVIDIA’s NVLink and NVSwitch have set the default expectation that scale-up AI interconnects require proprietary silicon. HPE Juniper Networking’s push to standards-based Ethernet at 260 TB/s of scale-up bandwidth is a wager that enterprise and sovereign buyers will prize interoperability and multi-vendor sourcing over the last increment of interconnect performance, particularly as AI infrastructure procurement becomes a matter of national policy rather than pure IT purchasing.
Government Workloads as the Proving Ground
ORNL’s Discovery and Lux systems, tied explicitly to the U.S. Genesis Mission, and HLRS’s Herder system in Germany, give HPE two sovereign-scale reference deployments before the GX5000 has any meaningful presence in commercial hyperscale accounts. That sequencing is consistent with HPE’s historical playbook of using DOE and European national-lab wins as the credibility layer before broader enterprise AI Factory positioning. The open question is how quickly performance and adoption data from these early deployments becomes available externally, since HPE’s density and efficiency claims are currently self-reported and have not yet been validated by an independent benchmark or a customer disclosure of production-scale results.
What to Watch:
- Whether independent benchmarks or customer performance data validate HPE’s density and efficiency claims once Discovery, Lux, and Herder come online.
- Whether AMD’s Helios/UALoE Ethernet approach gains traction against Nvidia’s NVLink-based scale-up fabrics in enterprise and sovereign AI procurement.
- Whether HPE converts its DOE and European national-lab wins into a broader enterprise AI Factory or hybrid cloud infrastructure deals beyond HPC-specialist accounts.
For more information, see the press release on HPE’s website.
Disclosure: Futurum is a research and advisory firm that engages or has engaged in research, analysis, and advisory services with many technology companies, including those mentioned in this article. The author does not hold any equity positions with any company mentioned in this article.
Analysis and opinions expressed herein are specific to the analyst individually and data and other information that might have been provided for validation, not those of Futurum as a whole.
Other Insights From Futurum:
AMD Helios Reaches Parity with Vera Rubin NVL72: Can Open Standards Outflank NVIDIA?
HPE Q2 FY 2026: AI Orders Remain Strong as Supply Constraints Persist
From Potential to Production: Enterprise AI with a Partner Ecosystem
Featured Image: HPE
Author Information
Alastair has made a twenty-year career out of helping people understand complex IT infrastructure and how to build solutions that fulfil business needs. Much of his career has included teaching official training courses for vendors, including HPE, VMware, and AWS. Alastair has written hundreds of analyst articles and papers exploring products and topics around on-premises infrastructure and virtualization and getting the most out of public cloud and hybrid infrastructure. Alastair has also been involved in community-driven, practitioner-led education through the vBrownBag podcast and the vBrownBag TechTalks.